Microsoft’s new speech models point to modular real-time voice agents
IA Mag
news
MAI-Transcribe-2-Streaming: Microsoft Real-Time Voice AI
DigitalToday
news
Microsoft unveils real-time transcription and speech synthesis models to support voice AI agent development
Interestana / MarkTechPost
news
Microsoft AI Releases MAI-Transcribe-2-Streaming Speech-to-Text Model
Three models
Microsoft AI introduced MAI-Transcribe-2-Streaming, MAI-Voice-2.1 and MAI-Voice-2.1-Flash as separate components for real-time voice-agent pipelines.
Streaming input
MAI-Transcribe-2-Streaming is designed to provide partial transcript updates while a speaker is still talking.
Preview risk
Public-preview availability through Microsoft Foundry and Azure Speech makes pilots easier, but enterprises still need to evaluate service commitments, cost and compliance fit.
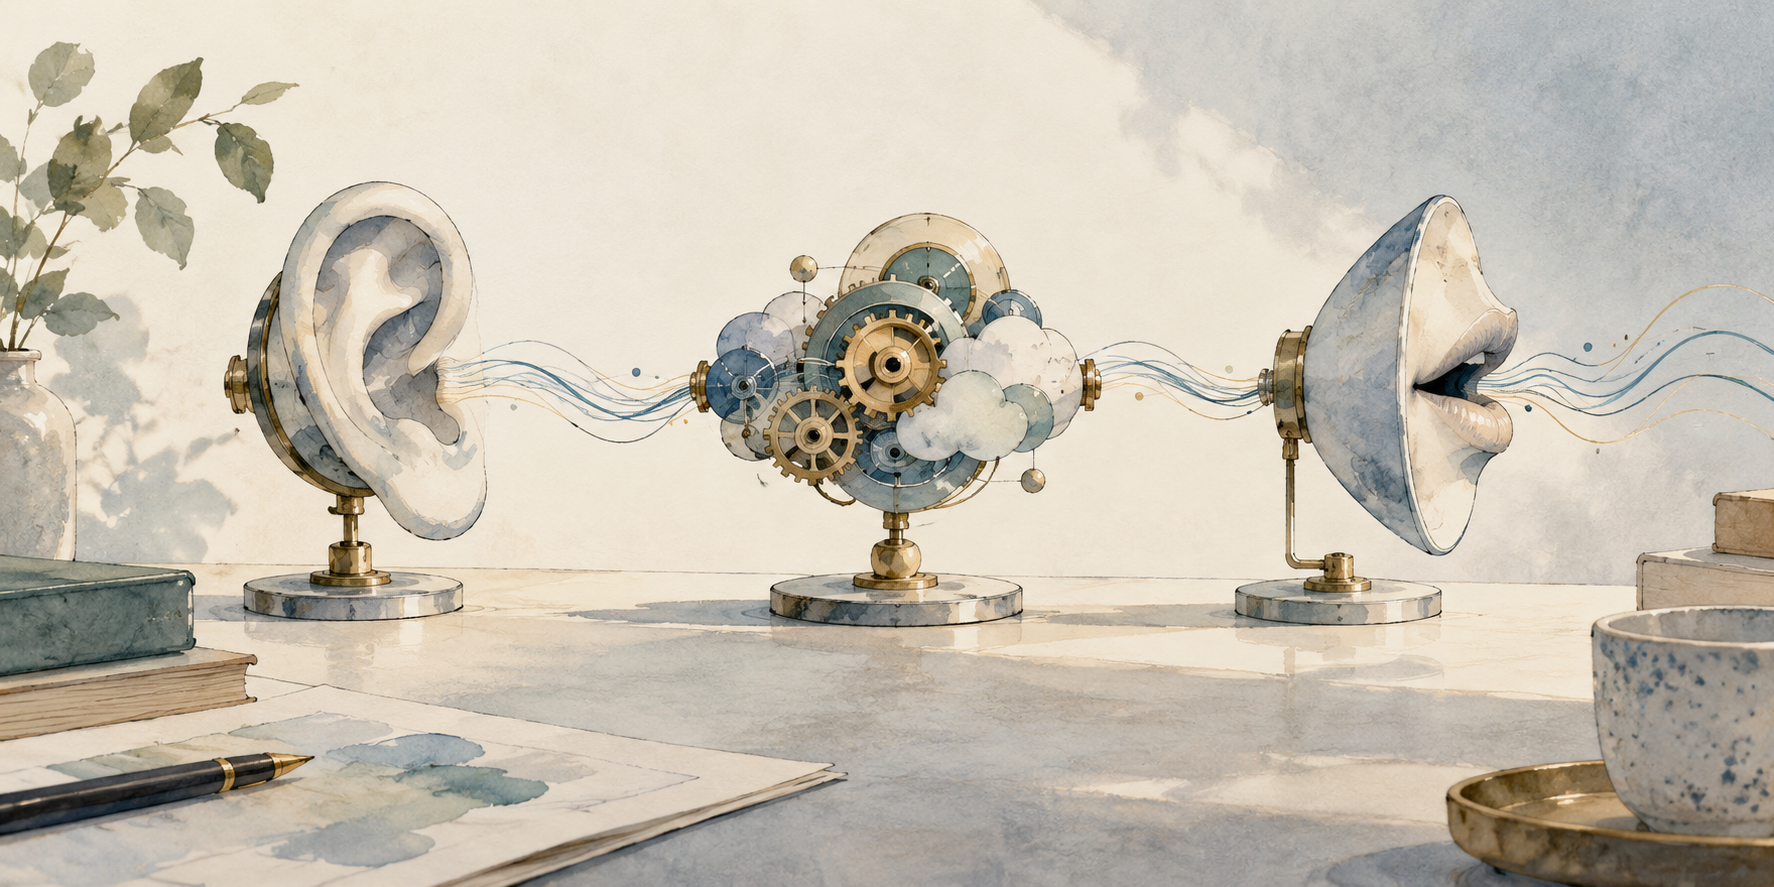
Microsoft AI’s release of MAI-Transcribe-2-Streaming, MAI-Voice-2.1 and MAI-Voice-2.1-Flash marks a practical shift in real-time voice-agent design. Speech input and speech output are becoming distinct, configurable layers in a latency-sensitive engineering stack, rather than features bundled around a single general-purpose model.1
Announced on October 1 and documented for public-preview use through Microsoft Foundry and Azure Speech, the three models split the voice-agent loop into specialized components: streaming speech-to-text for live input, multilingual text-to-speech for response generation, and a lower-latency Flash synthesis option for applications where response time matters more than maximum expressiveness.245 The result is a more modular architecture for developers building conversational agents, live captioning tools, meeting assistants, contact-center systems and other applications that need to listen, reason and speak in near real time.
The most important model in the launch is MAI-Transcribe-2-Streaming, a real-time automatic speech recognition model designed to produce partial transcript updates while a user is still speaking.13 That capability is central to modern voice-agent design because a downstream large language model or orchestration layer does not always need to wait for a final transcript before preparing a response, updating state or triggering a workflow. In practice, partial hypotheses can reduce perceived latency, support interruption handling and make spoken interfaces feel less like turn-based dictation systems.
Microsoft’s paired text-to-speech releases complete the other side of the loop. MAI-Voice-2.1 is positioned as a multilingual speech-synthesis model, while MAI-Voice-2.1-Flash is the faster variant for lower-latency output.24 For enterprise architects, that split matters: a customer-facing assistant might use the higher-quality voice for polished responses, while an operational workflow agent might choose the Flash path to keep conversations moving.
The launch reflects a broader architectural pattern in voice AI. A production-grade voice agent is usually not one model. It is a pipeline of audio capture, streaming transcription, endpointing, dialogue management, retrieval or tool use, safety controls, response generation, speech synthesis and observability. Microsoft’s new stack makes that separation explicit by offering different models for speech recognition and speech generation.47
That separation gives developers more control over tradeoffs. They can optimize transcription accuracy separately from output latency, tune when partial transcripts are passed downstream, and choose a text-to-speech model based on conversational urgency, cost, voice quality or language coverage. They can also swap components over time without redesigning the entire agent.
This is especially relevant for enterprises, where voice agents often have to connect with existing systems of record, compliance processes and contact-center infrastructure. A modular speech stack lets architecture teams isolate risk. The transcription component can be evaluated on word error rate, streaming latency and language performance. The reasoning layer can be evaluated on task completion and policy compliance. The speech-synthesis layer can be evaluated on latency, intelligibility, tone and brand fit.
Partial transcripts are not just a user-interface feature. They are an engineering primitive for low-latency voice AI. MAI-Transcribe-2-Streaming is described as generating real-time transcript updates and partial hypotheses as speech arrives, rather than waiting for a completed utterance.23
That changes how agents can behave. A travel assistant can begin resolving entities such as destination, dates and loyalty status before the speaker finishes. A support bot can detect rising frustration or a likely escalation request early. A meeting assistant can update captions continuously and revise them as acoustic confidence improves. In each case, the system can use provisional language understanding while preserving a final transcript for records, search or compliance.
The design challenge is that partial transcripts are inherently unstable. Words can be revised as the model receives more audio context. Developers therefore need orchestration logic that distinguishes provisional input from committed input. A well-designed agent should avoid taking irreversible action on uncertain partial text, while still using it to prepare candidate responses, retrieve likely context or pre-warm downstream tools.
Microsoft’s two MAI-Voice variants underscore that speech output is also becoming tunable. MAI-Voice-2.1 and MAI-Voice-2.1-Flash appear to target different points on the quality-latency curve, giving developers a choice between richer synthesis and faster delivery.24
That distinction matters because voice-agent latency is cumulative. Delays can come from audio capture, transcription, endpoint detection, model reasoning, retrieval, policy checks and speech synthesis. Even if the language model is fast, slow text-to-speech can make the overall experience feel sluggish. Faster synthesis can make an agent feel more responsive even when the reasoning layer remains unchanged.
For enterprise use cases, text-to-speech selection becomes an architectural decision rather than a cosmetic one. A banking assistant reading disclosures may prioritize clarity and consistency. A warehouse operations assistant may prioritize speed. A healthcare scheduling bot may require both low latency and carefully controlled tone. A modular TTS layer lets teams map the model choice to the workflow instead of accepting one default voice path for every scenario.
The models’ public-preview status is a key consideration for enterprise adoption. Reports on the launch describe support through Microsoft Foundry and Azure Speech, including integration paths through Azure Speech SDK and WebSocket-based workflows.57 That availability makes experimentation easier, but preview services typically carry different reliability, support and procurement assumptions than generally available production services.
For architects, the immediate use case is likely prototyping, benchmarking and controlled pilots rather than high-dependency production rollout. Teams can test whether streaming transcripts improve turn-taking, whether MAI-Voice-2.1-Flash materially reduces end-to-end latency, and whether the models meet language, domain and compliance requirements. They should also track service-level commitments, regional availability, data-handling terms and pricing changes before standardizing on the stack.
Pricing is another practical factor. Coverage of the launch notes transcription pricing and highlights that procurement teams should weigh accuracy gains against cost, preview risk and alternatives.26 That is particularly relevant for high-volume contact centers, captioning services and always-on meeting tools, where per-minute economics can quickly dominate model-selection decisions.
Several reports cite Artificial Analysis rankings and benchmark discussion around MAI-Transcribe-2-Streaming, including word error rate and latency comparisons.13 Those metrics are useful, but they do not fully determine whether a model is suitable for a given voice-agent deployment.
In real systems, transcription accuracy depends on accent mix, microphone quality, background noise, domain vocabulary, code-switching, call compression and interruption patterns. Latency also needs to be measured end to end, not only at the model boundary. A model that performs well in a benchmark may still require domain adaptation, glossary handling, post-processing or workflow-specific confidence thresholds.
The more meaningful benchmark for enterprise teams is task-level performance. Does the agent resolve more calls without escalation? Does it reduce average handle time without increasing errors? Does it improve accessibility for live meetings? Does it maintain compliance when partial transcripts are revised? Microsoft’s model releases provide new components for that evaluation, but the final answer depends on system design.
For AI developers, the launch points toward a more composable development model. A real-time agent can be assembled from streaming automatic speech recognition, a reasoning model or agent framework, tool integrations and one of several text-to-speech paths. Microsoft Foundry and Azure Speech give developers cloud-native entry points for testing those components together.57
That composability also creates new responsibilities. Developers need to handle partial transcript updates, cancellations, barge-in, turn detection, silence thresholds and transcript correction. They need to decide when the language model should start processing an utterance and when it should wait. They also need telemetry that separates transcription delay from reasoning delay and synthesis delay. Without that observability, it is difficult to know which part of the voice loop is responsible for a poor user experience.
The release reinforces a likely direction for voice-agent tooling: model selection will become dynamic. An agent might use a faster TTS model for acknowledgments such as “I’m checking that now,” then switch to a higher-quality model for longer explanatory responses. It might process partial transcripts for intent prediction while waiting for a final transcript before executing a financial transaction. It might choose different speech settings depending on language, device, network conditions or user preference.
For enterprise architects, Microsoft’s move makes the voice stack easier to map to familiar system-design concerns. Streaming transcription becomes an ingestion layer. The agent framework becomes a decision and orchestration layer. Text-to-speech becomes a delivery layer. Each layer can be evaluated, monitored and governed separately.
That separation supports stronger controls. Sensitive workflows can require final transcript confirmation before tool execution. Regulated industries can retain committed transcripts while discarding provisional hypotheses. Contact centers can A/B test synthesis models independently of the reasoning engine. Global organizations can evaluate language coverage separately for input and output.
It also makes vendor strategy more nuanced. Organizations may choose Microsoft’s full first-party stack for integration simplicity, especially if they already use Azure. Others may use Microsoft’s transcription model with a different agent framework, or Microsoft’s TTS models with an existing speech-recognition layer. The strategic question is no longer only which company has the strongest all-in-one voice agent. It is which components meet the enterprise’s latency, accuracy, compliance and cost requirements.
The October 1 launch is best understood as part of a broader move from demo-oriented voice bots to engineered real-time agents. MAI-Transcribe-2-Streaming addresses the input side by turning speech into continuously updated text. MAI-Voice-2.1 and MAI-Voice-2.1-Flash address the output side by giving developers speech-synthesis options with different performance characteristics.124
That architecture is less glamorous than a single end-to-end model, but it is closer to how enterprise systems are built. Real-time agents must be observable, governable, replaceable and cost-aware. They must handle interruptions, noisy environments, uncertain transcripts and multi-step workflows. Microsoft’s new speech models do not eliminate those engineering challenges, but they signal that the core building blocks of voice AI are becoming more specialized.
For developers and enterprise architects, the main takeaway is clear: the future of voice agents is a pipeline. The winners will not simply be the systems with the most natural voice or the strongest language model. They will be the systems that coordinate transcription, reasoning and synthesis with enough speed, accuracy and control to make spoken interaction reliable in production.
GitHub is unifying Copilot Chat, Copilot Mobile and the Copilot cloud agent into a more persistent agentic coding experience. For enterprise administrators, the immediate question is no longer whether developers can try AI agents, but how default-on agent capabilities should be governed, retained, audited and constrained.
Security researchers reported a malvertising cluster that used sponsored search ads, lookalike ChatGPT pages and Custom GPT-style interactions to push users into ClickFix malware execution paths. The campaign suggests attackers are moving beyond fake AI downloads and using trusted AI product surfaces as routing infrastructure.
Horizon3 said Anthropic’s Mythos helped identify CVE-2026-61500, a Rejetto HFS session-forgery flaw that can lead to unauthenticated remote code execution. VulnCheck said exploitation began on October 1, underscoring how quickly AI-assisted vulnerability research can move from code review to real-world attack monitoring.
Shopify’s new Canvas workspace lets merchants edit a live rendering of their storefront through Sidekick, moving AI storebuilding closer to direct theme-file modification than conventional no-code design. Its launch limits around third-party themes, app blocks, translations, Markets and rollouts show where developers remain central.
Streaming transcription
A speech-to-text approach that produces text while audio is still arriving, rather than waiting for the speaker to finish.
Partial transcript
A provisional transcript that may be revised as the model receives more audio context.
Text-to-speech
A model or system that converts written text into spoken audio.
Public preview
An early availability stage that lets developers test a service before it has the same maturity expectations as a generally available production release.
Comments